Tim Berners-Lee and the World Wide Web
Abstract
In 1989, a British physicist working at a particle physics laboratory in Switzerland submitted a proposal to his manager for a system to help researchers share information. His manager approved it with the handwritten annotation “Vague but exciting.” By Christmas 1990, the first working website existed. By April 1993, CERN had released the technology into the public domain, no patents, no royalties, for anyone, forever. Tim Berners-Lee had declined to become a billionaire in order to give the world the Web. He spent the following three decades watching what the world built with it and growing increasingly alarmed.
The CERN Problem
Timothy John Berners-Lee was born on June 8, 1955, in London. His parents were a matched pair of unusual distinction: Conway Berners-Lee and Mary Lee Woods had both worked on the Ferranti Mark 1, one of the first commercially sold computers, in the early 1950s. The dinner table, by his own account, was a place where mathematics and computing were the natural language of conversation. He studied physics at Queen’s College, Oxford, graduating in 1976, and spent his early career writing software for telecommunications companies.
In 1980, he joined CERN, the European Organization for Nuclear Research, the particle physics laboratory straddling the French-Swiss border near Geneva, as an independent contractor, from June to December 1980. The scale of the place was staggering. CERN employed thousands of researchers from dozens of countries. Accelerators such as the Super Proton Synchrotron, nearly seven kilometres around, were supervised by shifting teams of physicists who arrived on two-year contracts, absorbed years of institutional knowledge, and left, taking that knowledge with them. Connecting a new researcher to the understanding of what existed and who knew what was a problem no filing system had solved.
Berners-Lee’s first attempt was personal. He wrote a program he called ENQUIRE, named after an old Victorian domestic encyclopedia he remembered from his parents’ bookshelf, Enquire Within Upon Everything. ENQUIRE organized information as a network of nodes connected by typed links: a person linked to the projects they worked on, which linked to the software those projects used, which linked to the computers that software ran on. It was a small hypertext system, running on one computer, with no external connections.
He left CERN at the end of 1980, worked elsewhere for four years, and returned in 1984 as a fellow. ENQUIRE had been lost. But the problem it had tried to solve had only grown larger.
The lost program taught him the design lesson at the heart of the Web. The first ENQUIRE could link between files as easily as within them; a later port dropped external links, and Berners-Lee found the constraint debilitating: hypertext confined to database enclosures could not model the “changing morass of relationships” that characterized a place like CERN. His requirement for the next system was that an external link must be exactly as easy to make as an internal one, and that two separately grown webs must merge by simply adding links between them, with no central database to reconcile. That requirement forced links to be one-way, with no guarantee the target still existed. The dangling link, later cursed as the “404 Not Found” error, was the price of a system that could scale without anyone’s permission.
“Vague but Exciting”: The 1989 Proposal
In March 1989, Berners-Lee submitted a formal proposal to his manager, Mike Sendall, titled “Information Management: A Proposal.” The document described a global hypertext system in which documents on networked computers could contain clickable links to documents on any other networked computer. A physicist at CERN could write a document, embed in it a reference to another document held on a computer in another building or another country, and a reader clicking that reference would be taken directly to it.
Sendall returned the proposal with a note in the margin: “Vague but exciting.” There was no formal project, but in 1990 Sendall let him buy a NeXT workstation and start building it.
The system that grew out of the proposal rested on three ideas. First, hypertext (documents containing links to other documents) would provide the navigational structure. Vannevar Bush had theorized this in 1945, and Douglas Engelbart had demonstrated it in 1968, but both implementations required users to be inside a specific system. Berners-Lee proposed extending it across the open internet, which meant the links could connect documents on any computer anywhere.
Second, every document would have a unique, persistent address (a Uniform Resource Locator, or URL) that specified exactly where it lived on the network. This made linking reliable: you could write a link, share it with another person months later, and it would still point to the same thing.
The URL’s odd punctuation was assembled from things Berners-Lee expected people to recognize. The path slashes are Unix pathname syntax “reused without apology.” The double slash before the hostname he copied from the network filesystem of Apollo workstations, which wrote //computername/file/path. The # separating a fragment from its document came from postal addresses, where “12 Acacia Av #12” means a unit within a building; he later learned that Douglas Engelbart’s NLS had independently chosen # for the same job. One choice he came to regret: the double slash turned out to be unnecessary, and in 2009 he offered a lighthearted public apology for it (“it seemed like a good idea at the time”).
Third, documents would be written in a simple markup language (HTML, HyperText Markup Language) that any software could parse and display. HTML was deliberately simple, even crude: it described structure (this is a heading, this is a paragraph, this is a link) rather than appearance, leaving rendering to the browser. A document that could be rendered by a simple program on any computer was a document that could reach everyone.
Info
Berners-Lee built on the internet infrastructure that already existed, the TCP/IP protocols that Cerf and Kahn had designed. He did not build a new network; he built an application layer on top of the existing one. HTTP (HyperText Transfer Protocol), the protocol browsers use to request web pages, runs over TCP/IP. The Web is not the internet; it is one of many applications that run on the internet. Berners-Lee’s contribution was the application layer that made the internet comprehensible and navigable for ordinary people.
In November 1990, Berners-Lee submitted a revised proposal with Belgian computer scientist Robert Cailliau. It included a full system architecture: a server program, a client program (the browser), the HTTP protocol, and HTML. The computing environment at CERN favored a specific machine: the NeXT workstation, manufactured by Steve Jobs’s company after his departure from Apple, running an object-oriented operating system that made software development unusually fast. Berners-Lee wrote the first web server and the first web browser (called WorldWideWeb) on a NeXT.
The name almost turned out differently. Berners-Lee wanted to stress the decentralized form in which anything could link to anything, mathematically a graph, or web. Candidates he considered and discarded: “Mine of Information” (in French, MOI, “a bit egotistical”), “The Information Mine” (whose initials spell TIM, “even more egocentric”), and “Information Mesh” (too close to “mess”). World Wide Web survived, three separate words, no hyphens, abbreviated W3 in the early documentation, which is why the standards body is the W3C and not the WWWC.
Myth: Robert Cailliau co-invented the World Wide Web.
He did not, and Berners-Lee has said so explicitly: the idea, the specifications for URLs, HTML, and HTTP, and the code of the first browser and server were Berners-Lee’s alone, and Cailliau joined more than a year after the March 1989 proposal. Cailliau’s contributions were different and real: he wrote the proposal that got CERN staff allocated to the project, spent 18 months lobbying the directorate for the royalty-free release of 1993, organized the first international WWW conference at CERN in 1994, and wrote an early Mac browser (Samba, with Nicola Pellow). Advocate, organizer, and first convert, not co-inventor. See Myths and Misconceptions.
Coding began in September 1990. In mid-November the first HTTP client and server talked to each other over the Internet, and on 20 December 1990 the first website went up on his NeXT workstation. The server had a handwritten label taped to it: “This machine is a server. DO NOT POWER IT DOWN!!”
The First Website
The first website was info.cern.ch. It described the World Wide Web project itself. Berners-Lee presented the project at a CERN seminar on 12 June 1991, and on August 6, 1991, posted to the alt.hypertext Usenet newsgroup announcing that the software (server and browser) was publicly available for download. Anyone could run a website.
The markup language had no formal specification yet. Its first public description was a short page called “HTML Tags”, which Berners-Lee first mentioned on the Internet in late 1991. It listed 18 elements, among them <title>, <a>, <p>, the headings <h1> to <h6>, and lists. Apart from the hyperlink anchor, they were borrowed from CERN SGML, an in-house documentation format, and eleven of them were still part of HTML 4. HTML became a formal standard only on November 24, 1995, as HTML 2.0 (RFC 1866).
Adoption was slow at first. Berners-Lee’s own WorldWideWeb browser was a point-and-click editor as much as a browser, with mode-free link creation and multiple fonts, but it ran only on NeXT machines, of which the world had few. What most people could access was the line-mode browser, written in late 1990 by Nicola Pellow, a mathematics undergraduate on an internship from Leicester Polytechnic: a text-only client, portable to almost anything, with links indicated by numbers in brackets. Many early users concluded from it that the Web was “a way of finding information by typing numbers.” On 12 December 1991 SLAC in California put up the first web server outside Europe, giving physicists access to its SPIRES database. Counts for the end of 1992 range from 26 to about 50 servers worldwide.
Browsers written by outsiders carried the Web to its next users in 1992 and 1993. Four students at Helsinki University of Technology released Erwise in April, the first graphical browser for the X Window System; they graduated, no funding appeared, and development stopped, not helped by code documented in Finnish. Pei-Yuan Wei, a student at UC Berkeley, released ViolaWWW in March and kept improving it: it had scriptable embedded objects, stylesheets, and tables years before those features had standard names, and for a stretch it was the browser CERN recommended. Tony Johnson at SLAC wrote Midas; Tom Bruce at Cornell released Cello for the PC in June 1993. Pellow, back at CERN after graduating, wrote the first Mac browser (MacWWW, also called Samba) with Robert Cailliau.
The inflection point came with Mosaic, the graphical browser written by Marc Andreessen and Eric Bina at the University of Illinois in early 1993. Mosaic displayed images inline with text, was trivial to install, came with Andreessen answering support mail around the clock, and from late 1993 also ran on the Windows and Mac computers that most people actually owned. Within months of Mosaic’s release, the web was growing at a rate of several hundred percent per year.
The Public Domain Decision
As the web’s growth became visible, CERN faced a decision. The technology Berners-Lee had developed on company time, using company resources, was clearly valuable. The institution could patent HTTP, HTML, and the URL format, could charge licensing fees for every website, every browser, every server. The revenue would be substantial.
Berners-Lee argued forcefully against it. The web’s value came entirely from its universality: it was useful because everyone could use it and everyone could build on it. A licensed web would fragment into competing proprietary systems, each incompatible with the others, exactly the fate that had befallen earlier attempts at distributed information systems. The royalties that would be earned in the short term would be dwarfed by the value destroyed in the long term.
On April 30, 1993, CERN officially released all World Wide Web technology into the public domain. No patents. No royalties. No restrictions. Anyone could implement HTML, HTTP, or URL handling without asking permission or paying fees.
Berners-Lee’s own explanation was short: “You can’t propose that something be a universal space and at the same time keep control of it.”
Myth: Tim Berners-Lee became a billionaire from inventing the Web.
He did the opposite. Berners-Lee and CERN deliberately released HTTP, HTML, and the URL into the public domain in 1993 with no patents and no royalties, precisely so the Web would become a universal open standard rather than a proprietary “walled garden.” Charging for it would have fragmented the Web into incompatible licensed systems and destroyed the universality that made it valuable. See Myths and Misconceptions.
The first International World-Wide Web Conference, organised by Robert Cailliau, was held at CERN from 25 to 27 May 1994: more than 600 people applied, the hall held 380, and Andreessen, Bina and Berners-Lee were among the first inducted into a World Wide Web Hall of Fame. The phrase for using it had appeared two years before, in the librarian Jean Armour Polly’s article “Surfing the Internet” in the Wilson Library Bulletin of June 1992. On 1 October 1994, he founded the World Wide Web Consortium (W3C) at MIT, with funding from DARPA and the European Commission, to develop and maintain open web standards. The W3C’s model (consensus-based standardization, with participation from companies and institutions but no single controlling party) has governed the evolution of HTML, CSS, JavaScript APIs, and the web platform ever since. Berners-Lee served as director of the W3C from its founding until the consortium reincorporated as a public-interest nonprofit in January 2023, when he became its Emeritus Director. That tenure of nearly three decades gave him unusual influence over the web’s technical direction.
The web also had a direct competitor for the same job, backed by a university and briefly more popular: see Dead End: Gopher.
Dead End: The Semantic Web
Berners-Lee’s technical ambitions for the web extended far beyond documents and links. In a 1999 book and a famous 2001 Scientific American article, he described a vision he called the Semantic Web: a next-generation web in which data would carry machine-readable meaning, expressed using formal vocabularies so that software agents could reason about it autonomously. A travel agent program could query multiple flight databases, hotel systems, and review sites, combining information from sources that had never been explicitly connected, because all the data would be expressed in interoperable formats.
The Semantic Web proposed a technical stack: RDF (Resource Description Framework) for expressing data relationships, OWL (Web Ontology Language) for defining shared vocabularies, and SPARQL for querying RDF stores. W3C standardized all of these. Academic researchers published thousands of papers. Funding agencies invested.
Warning
The Semantic Web failed to achieve mainstream adoption for interlocking technical and economic reasons. Producing correct semantic markup required sustained expert effort. Individual websites had no incentive to annotate their data for competitors’ benefit, a company that carefully structured its product data in RDF would be making it easier for comparison engines to extract that data and direct customers to cheaper alternatives. The ontology standards were complex enough that only specialists could use them correctly, and specialists who disagreed about ontology design fought prolonged technical battles. Meanwhile, the practical problems the Semantic Web was meant to solve (cross-source information integration) were being addressed more cheaply by statistical machine learning and search engines that inferred structure without requiring it to be explicitly declared. What did succeed was a minimal subset: schema.org (2011), launched by Google, Bing, and Yahoo, provided a simplified vocabulary for structured data embeddable in ordinary HTML. This was far less ambitious than Berners-Lee’s vision, but it was what the market found tractable.
The Web He Didn’t Build
By the 2010s, Berners-Lee had become one of the most prominent critics of what the web had become. The open, decentralized network he had envisioned (where anyone could publish, anyone could link, no organization controlled access to information) had been substantially colonized by a handful of platforms. Facebook, Google, and Amazon mediated the experience of most web users. Their systems were designed to maximize engagement and data collection, not to serve user interests. The personal data generated by billions of people had become the raw material for surveillance capitalism on a scale that made earlier forms of commercial data collection look artisanal.
His responses were institutional and technical. In November 2018 he announced the “Contract for the Web”, a set of principles for governments, companies, and citizens about protecting the open web; the full contract was published in November 2019, endorsed by more than 150 organizations. The contract had no enforcement mechanism; it was a statement of values.
More technically ambitious was the Solid project: an open-source platform Berners-Lee developed through his spinout company Inrupt, allowing individuals to store their personal data in “pods” (personal online data stores that they controlled) and grant specific applications permission to access specific data. Rather than surrendering all data to a platform in exchange for services, a Solid user would retain their data and extend fine-grained permission to applications that needed it. Berners-Lee described Solid as the web he had originally meant to build.
Solid remained a research and early-adopter project through the mid-2020s. Its adoption was limited by the familiar bootstrapping problem: the value of a data infrastructure depends on how many services use it, and services won’t invest in supporting an infrastructure that isn’t widely adopted.
Recognition
Berners-Lee was appointed Knight Commander of the Order of the British Empire (KBE) in 2004 (making him Sir Tim) in recognition of services to the global development of the internet. He received the 2016 Turing Award “for inventing the World Wide Web, the first web browser, and the fundamental protocols and algorithms allowing the Web to scale.”
At the opening ceremony of the 2012 London Olympics, in front of 80,000 spectators and a global television audience, Berners-Lee sat at a vintage NeXT computer and tweeted a message that lit up in LEDs on the audience seats: “This is for everyone.”
He had said the same thing with CERN’s public domain decision in 1993. The 2012 display made it visible to billions of people at once.
The browsers that brought his invention to mass audiences are covered in Marc Andreessen and Netscape and Mitchell Baker and Mozilla; the Browser Wars in The Browser Wars; the network infrastructure the Web runs on in The Connected World.
📚 Sources
- Heinz Nixdorf MuseumsForum blog, “Wie das Web weltweit wurde” (5 August 2016) and “Wolkig aber aufregend – wie das Web geboren wurde” (12 March 2019) (the 1991 seminar and announcement, the 1989 proposal)
- Heinz Nixdorf MuseumsForum blog, “Das Woodstock des World Wide Web” (28 May 2024), "„Today we’ll surf the net.“" (3 June 2022) and “Happy Birthday, W3C !” (1 October 2019) (WWW1, Polly’s 1992 article, the W3C)
- Berners-Lee, Tim: Weaving the Web: The Original Design and Ultimate Destiny of the World Wide Web (1999), HarperCollins
- Berners-Lee, Tim: Information Management: A Proposal (1989), CERN
- Berners-Lee, Tim, Hendler, James & Lassila, Ora: The Semantic Web (2001), Scientific American
- Gillies, James & Cailliau, Robert: How the Web Was Born (2000), Oxford University Press
- Zuboff, Shoshana: The Age of Surveillance Capitalism (2019), PublicAffairs
- W3C: A Little History of the World Wide Web
- Berners-Lee, Tim: “Frequently asked questions” — w3.org (his own press FAQ: name candidates, // and # origins, Enquire lesson, first browsers, Cailliau’s role)
- CERN timeline: “First web server outside Europe” (SLAC, 12 December 1991)
- historyofinformation.com: “According to Robert Cailliau, There are 50 Web Servers on the Internet”
- Wikipedia: Cello (web browser) (first release 8 June 1993)
- ACM A.M. Turing Award: Tim Berners-Lee (2016 citation)
- Wikipedia: Nicola Pellow (line-mode browser, MacWWW)
- Wikipedia: ViolaWWW (Pei-Yuan Wei, March 1992)
- Wikipedia: Erwise (Helsinki, April 1992)
- Wikipedia: Tim Berners-Lee (2009 double-slash apology)
- W3C re-launched as a public-interest non-profit organization (January 2023) — W3C press release (Berners-Lee becomes Emeritus Director)
- Berners-Lee, Tim: “HTML Tags” — W3C archive of the 1992 CERN web
- HTML — Wikipedia (History: “HTML Tags” first mentioned late 1991, 18 elements, CERN SGML, HTML 2.0 as RFC 1866)
- Berners-Lee, T. and Connolly, D.: RFC 1866, “Hypertext Markup Language - 2.0” (November 1995)
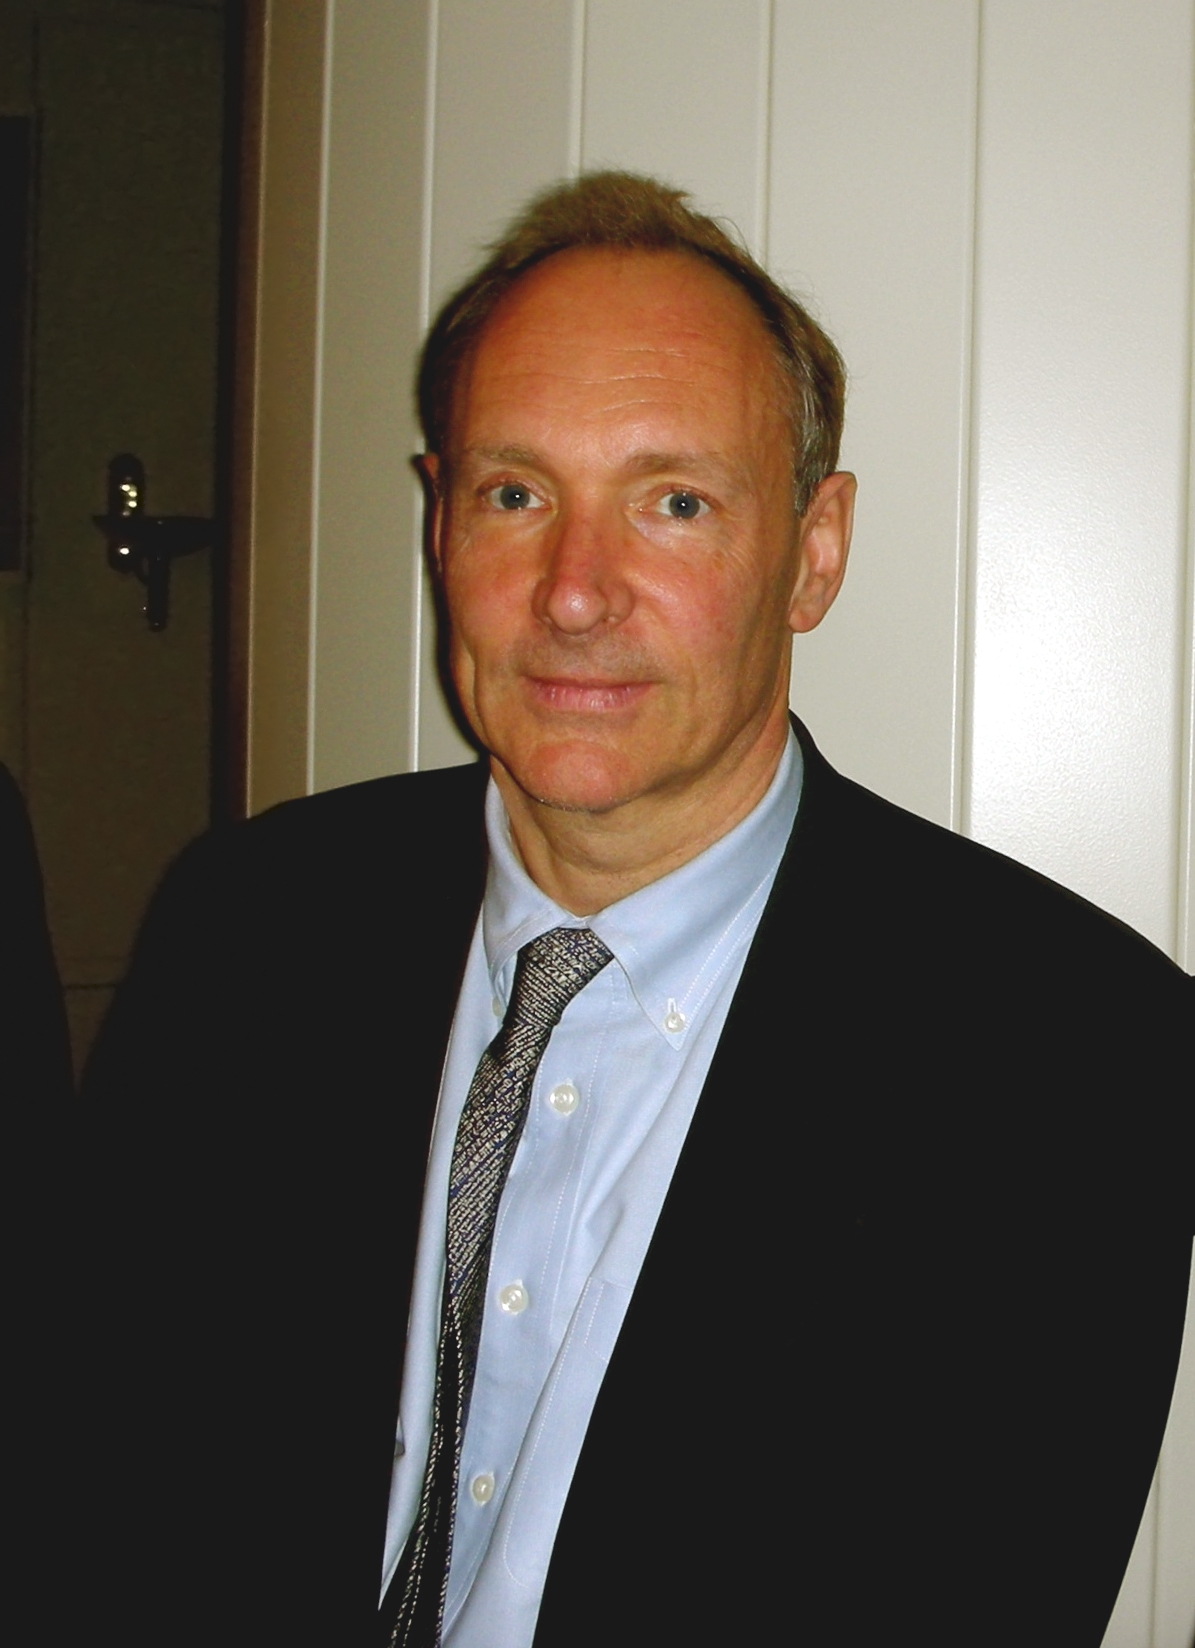
- Image: Tim Berners-Lee April 2009.jpg by Enrique Dans (CC BY 2.0), via Wikimedia Commons